02Writing
Essays, with illustrations.
Notes on attention, embeddings, LLMs, and the everyday strangeness of training neural networks on a budget.
- 07March 8, 2026·15 min read
Pre-training a 95M Parameter LLM on a Consumer GPU
LLMPyTorchPre-trainingMixed PrecisionTransformerDeep LearningGPUMachine Learning
- 06January 11, 2026·10 min read
Writing CUDA Kernels from Scratch: A Beginner's Guide
CUDAGPU ProgrammingMatrix MultiplicationDeep LearningPerformance OptimizationC++High Performance Computing
- 05April 12, 2025·8 min read
Llama 2 Explained
LlamaMeta AILlama2LLMTransformerGrouped-Query AttentionKV CacheAttentionMachine LearningDeep Learning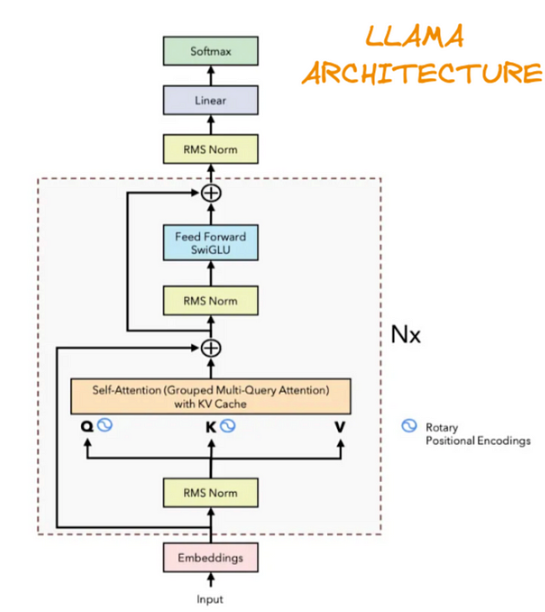
- 04April 5, 2025·5 min read
Llama 4: The Natively Multimodal AI
LlamaMeta AILlama4LLMMultimodal AIMixture of Experts (MoE)AttentionGenerative AIMachine LearningDeep Learning
- 03March 24, 2025·20 min read
Attention and the versions of it: Layer by Layer
Attention MechanismTransformersSelf-AttentionSDPADeep LearningMachine LearningFlash AttentionSliding Window AttentionInfini-AttentionGrouped Query Attention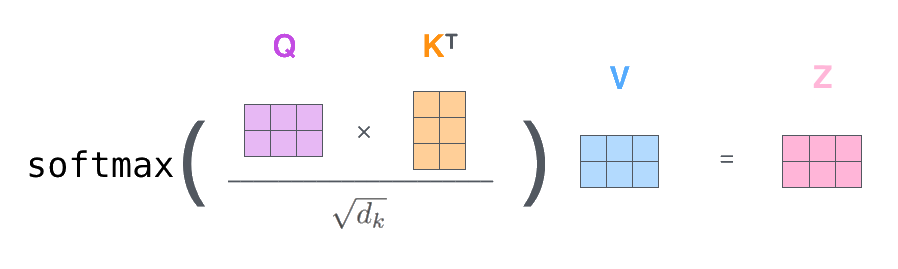
- 02March 20, 2025·6 min read
Attention: Explanation is All You Need
Attention MechanismTransformersSelf-AttentionMachine LearningDeep LearningLLMs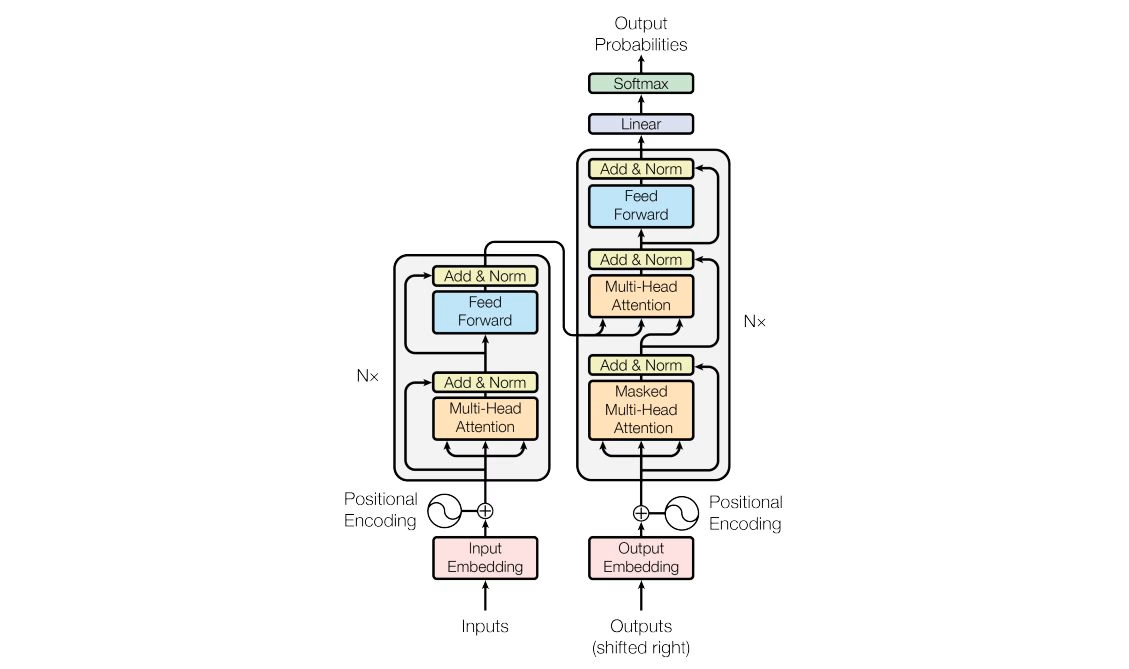
- 01March 13, 2025·4 min read
From Words to Meaning: The Journey From Word Vectors to Learnable Embeddings
Machine LearningDeep LearningData ScienceLLMsWord EmbeddingsVector Embeddings